
You’re a founder or product lead, and customers keep asking for “an AI assistant inside the app” to summarize documents, answer questions from company knowledge, and generate content fast. Building your own model stack feels expensive and slow—so you need a platform that gives you strong models, simple APIs, and practical features out of the box.
That’s exactly the gap Mistral AI is filling: it offers a consumer-facing assistant (Le Chat) plus a developer platform and models you can use via API. Mistral also positions itself around making advanced AI more accessible through its platform releases and tools.
Quick origin story: Mistral AI is a Mistral AI founded in 2023 and based in Paris. It has raised major funding rounds as it scaled its model lineup and platform offerings.
By the end of this guide, you’ll understand what Mistral AI is, how Le Chat and the Mistral API work step by step, how the business model and pricing are structured, what features drive adoption, and what it takes to build a similar AI platform for your niche—plus where Miracuves can help you launch faster.
What is Mistral AI? The Simple Explanation
Mistral AI is an AI company that builds powerful language models and offers them in two practical ways: a user-friendly assistant called Le Chat, and developer APIs (through its platform) that let businesses add AI features inside their own apps—like chat, writing help, summarization, and document Q&A.
The core problem it solves
Most teams want AI inside their product, but they don’t want to spend months training models or building infrastructure. Mistral’s platform approach helps by providing ready-to-use models plus a simple way to integrate them through APIs and tooling—so you can focus on your product experience, not the AI plumbing.
Target users and common use cases
Mistral AI is used by:
- Startups building AI-first apps
- SaaS companies adding AI features (assistants, summarizers, content tools)
- Enterprises that want customization, privacy, and control
Common use cases include: chatting with an assistant (Le Chat) and building AI features through the API for production applications.
Current market position with stats
Mistral is positioned as a major European AI player. Reporting highlights significant fundraising, including a €600M round in 2024, and later reporting also points to much larger rounds and valuations as it scaled.
Why it became successful
It grew fast because it combined three things companies care about:
- High-demand AI models + developer access via APIs
- A consumer-friendly entry point (Le Chat) to experience the models
- Clear packaging of offerings and plans (pricing + tiers) for individuals and teams
How Does Mistral AI Work? Step-by-Step Breakdown
For users (developers, product teams)
Account creation process
- Create an account in Mistral’s console and set up payment details.
- Generate an API key.
- Use that key to call Mistral’s API endpoints (chat/completions, embeddings, etc.).
Main features walkthrough (what you typically build)
Most teams use Mistral AI for a few core product experiences:
- Chat assistants inside apps (support, internal helpdesk, product copilot) via chat/completion endpoints.
- Content workflows (summaries, rewrite, extraction, drafting).
- Semantic search and RAG building blocks using embeddings endpoints (turn text into vectors so you can retrieve relevant info).
- Team productivity with Le Chat (customizable assistant with privacy/control positioning).
Typical user journey (simple example)
Let’s say you’re building “Ask Our Docs” for your SaaS:
- You upload product docs into your system
- You generate embeddings for those docs and store them in a vector database
- User asks a question
- Your system retrieves the most relevant doc chunks (by similarity)
- You send the user question + top doc chunks into Mistral’s chat/completion endpoint
- Mistral returns a grounded answer your UI displays to the user
Key functionalities explained (in plain English)
- Chat/Completion APIs: you send messages/instructions, the model generates a response.
- Embeddings: you convert text into “meaning vectors” so search works by intent, not keywords.
- Developer platform console: where you manage keys, usage, and integration setup.
For service providers (if applicable)
Mistral AI isn’t a marketplace like Uber, so “service providers” usually means your company offering an AI feature to your users.
Onboarding process
You set up the Mistral account, create keys, pick the endpoints you need (chat/completions, embeddings), and integrate from your backend so keys stay secure.
How you operate on the platform
You typically run a simple pipeline:
- Index your knowledge (docs → embeddings → vector DB)
- Retrieve relevant chunks per question
- Generate a final answer using chat/completions with that retrieved context
Earnings/Commission structure
There’s no “commission.” You pay Mistral based on usage/pricing tiers, then you decide how to charge your users (subscription, per-seat, usage add-on). Mistral publishes plan and pricing pages for Le Chat and platform usage.
Technical Overview (Simple)
At a high level, Mistral AI works like this:
- Your app sends a request to the API (prompt/messages)
- The model processes it and generates an output
- For knowledge-based answers, you add an embeddings + retrieval step before generation so responses stay grounded
Read More :- How to Develop an AI Chatbot Platform
Mistral AI’s Business Model Explained
How Mistral AI makes money (all revenue streams)
Mistral AI monetizes in a few practical ways:
- API usage from developers and businesses using Mistral models through the platform (pay for consumption).
- Paid plans for Le Chat (individual and team tiers) that bundle premium features and higher limits.
- Enterprise offerings (typically contract-based) for organizations that need governance, security, support, and scalable deployments.
Pricing structure with current rates
Mistral publishes pricing for both its consumer/product side (Le Chat plans) and its platform/API side (model usage). The exact price you pay depends on:
- which model you use
- how much input/output you send (token-based billing is the common structure for LLM APIs)
- any plan tier or enterprise contract terms
Fee breakdown (what you’re effectively paying for)
Unlike marketplaces, there’s no commission split. Costs usually map to:
- model usage (your requests and generated outputs)
- higher limits / premium features (often via plan tiers)
- enterprise-grade requirements (security, governance, support)
Market size and growth signals
Mistral’s fast growth is strongly linked to business demand for reliable AI platforms and Europe-based AI options. Reuters reported major fundraising, including a €600M round in 2024, signaling strong investor confidence and expansion momentum.
Profit margins insights
Like most AI API businesses, healthier margins typically come from:
- repeat enterprise contracts with predictable volumes
- efficient infrastructure utilization (serving more requests per unit compute)
- customers optimizing prompts/context and choosing models wisely (reducing wasted tokens)
Revenue model breakdown
| Revenue stream | What it includes | Who pays | How it scales |
|---|---|---|---|
| API usage | Calls to chat/completions, embeddings, etc. via Mistral platform | Developers, startups, enterprises | Scales with request volume and tokens |
| Le Chat paid plans | Premium assistant features and higher limits | Individuals and teams | Scales with subscribers/seats |
| Enterprise contracts | Governance, security, support, custom terms | Large orgs | Larger deal sizes + long retention |
Key Features That Make Mistral AI Successful
1) Le Chat as an easy entry point for everyday users
Why it matters: People adopt AI faster when it’s simple to try and instantly useful (no setup, no coding).
How it benefits users: Users can draft, summarize, and ask questions in a chat-style interface without needing a developer workflow.
Technical innovation involved: A consumer-facing assistant product layer (Le Chat) built on top of Mistral’s models and platform capabilities.
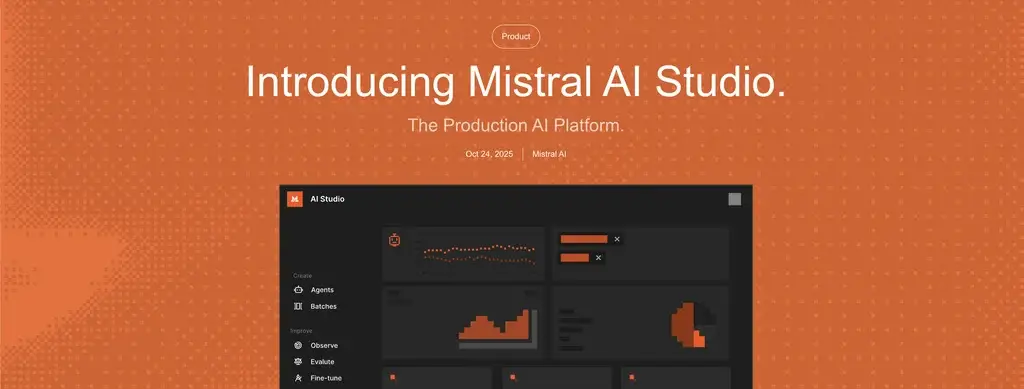
2) Mistral AI Studio for building and shipping use cases
Why it matters: Businesses don’t just want a model—they want a practical way to manage AI projects and deploy safely.
How it benefits users: Teams can create use cases, manage lifecycle, and ship AI features with privacy/security emphasis.
Technical innovation involved: A production platform (Studio) positioned around enterprise privacy, security, and data ownership.
3) Clean API layer for chat/completions (developer-friendly)
Why it matters: The faster a team can integrate, the faster they can launch features and test ROI.
How it benefits users: Developers can plug AI into apps for chat, summarization, extraction, and drafting with predictable API patterns.
Technical innovation involved: Documented Chat Completions capabilities and API specs for consistent request/response behavior.
4) Embeddings endpoint for semantic search and RAG
Why it matters: Most enterprise AI needs to answer using internal documents, not guess.
How it benefits users: Better “search by meaning” and stronger RAG pipelines for doc Q&A and internal assistants.
Technical innovation involved: Embeddings endpoints that accept single or bulk inputs and return vector representations for retrieval systems.
5) Structured control options inside API requests
Why it matters: In production, teams need consistency and controllability (not random outputs).
How it benefits users: More repeatable behavior across runs and better alignment with product requirements.
Technical innovation involved: API parameters like random_seed and intent-style controls (e.g., prompt_mode) exposed in the API spec.
6) Pricing and tiers for both users and builders
Why it matters: AI adoption grows when users can start free/low-cost and scale when value is proven.
How it benefits users: Individuals can try Le Chat, while teams and enterprises can move into paid tiers and higher limits as needed.
Technical innovation involved: Clear plan-based packaging (Le Chat + Studio tiers) published on official pricing pages and help docs.
7) Fast scaling and strong funding momentum (market confidence)
Why it matters: In AI platforms, customers worry about longevity—funding and growth signals matter for trust.
How it benefits users: Greater confidence that the platform will keep improving, expanding compute, and supporting enterprise needs.
Technical innovation involved: Investment used to expand compute resources and international presence (as reported).
8) Enterprise positioning (privacy, security, data ownership messaging)
Why it matters: Many organizations need governance and data control before they can deploy AI widely.
How it benefits users: Easier internal approval for adopting AI in regulated or sensitive environments.
Technical innovation involved: Product positioning and platform features emphasizing privacy/security and ownership of data.
9) One ecosystem: consumer assistant + developer platform
Why it matters: Consumer usage drives awareness, while the platform enables monetization through real business integrations.
How it benefits users: Users discover value via Le Chat; companies then operationalize the same capability through APIs and Studio.
Technical innovation involved: A two-layer product strategy (Le Chat + Studio/API) described across Mistral product and docs pages.
10) Focus on cost efficiency as a competitive lever
Why it matters: Cost is often the deciding factor when scaling AI features to millions of requests.
How it benefits users: Lower per-request costs can make AI features profitable rather than a burn.
Technical innovation involved: Mistral has publicly announced price reductions and platform updates aimed at broader, cheaper usage.
The Technology Behind Mistral AI
Tech stack overview (simplified)
Mistral AI is built around a straightforward platform idea: powerful models + clean APIs + products that make those models easy to use. The technical foundation usually includes a chat/completions-style interface for generation and an embeddings endpoint for retrieval-style apps.
Real-time features explained (how Mistral fits inside live apps)
Most Mistral-powered applications run in a real-time loop like this: a user asks something in your product, your backend sends a request to Mistral’s chat endpoint, and you return the answer to the UI. In practice, the API lets you control response length with parameters like max tokens, which matters for latency and cost.
If you’re building “chat with documents,” you typically add a retrieval step: you embed your documents, store them in a vector database, retrieve the most relevant chunks for each question, then pass those chunks into the chat prompt as context. The embeddings endpoint exists specifically to support this kind of semantic search and RAG workflow.
Output control and consistency (why this matters in production)
Production apps need repeatable behavior. Mistral’s API includes controls like random_seed for deterministic results when you want stability across runs (useful for testing and consistent automation).
It also exposes prompt_mode options (including a “reasoning” mode) as a high-level intent signal for the chat completion endpoint, which helps guide the assistant’s response style for different tasks.
Data handling and privacy (what teams typically implement)
In most real products, the safest pattern is to call Mistral from your backend (not directly from the mobile app/web browser), so your API keys stay private and you can apply your own governance. Mistral also positions Le Chat around privacy and control as a product principle, especially for teams.
Scalability approach (how Mistral apps handle growth)
Scaling usually comes down to reducing unnecessary tokens and keeping context tight. The chat endpoint’s context + max token limits encourage teams to be intentional about what they send, which helps keep response times stable and costs predictable.
For RAG-style products, scalability is mostly your retrieval engineering: good chunking, fast vector search, and only injecting the top evidence into the chat request.
Mobile app vs web platform (how builders ship it)
Most teams ship Mistral features like this:
Frontend (web/mobile) captures the request → backend validates permissions and fetches any relevant context → backend calls Mistral chat/embeddings → frontend displays the result. This pattern keeps keys safe, supports role-based access, and lets you log usage for cost control.
API integrations (where Mistral becomes powerful)
Mistral is most useful when it’s connected to real business systems. Common integrations include internal docs, support tickets, product knowledge bases, and analytics workflows—typically by combining embeddings + retrieval with chat completions for final answers.
Why this tech matters for business
Mistral’s tech matters because it supports a practical path from “AI experiment” to “AI feature”: you can build generation features quickly, and you can build more trustworthy knowledge assistants by grounding responses in retrieved content via embeddings.
Mistral AI’s Impact & Market Opportunity
Industry disruption it caused
Mistral AI pushed an important shift in the AI market: serious AI doesn’t have to be “only Silicon Valley-led.” It helped normalize the idea of a strong Europe-based AI platform that offers both a consumer assistant experience and developer/enterprise deployment options, including privacy- and sovereignty-focused messaging that resonates with regulated industries and governments.
It also raised the bar on what users expect from an assistant: not just chatting, but getting practical work done (search, document help, productivity flows). For example, updates to Le Chat introduced capabilities like web search with citations and editing/canvas-style workflows (reported in 2024).
Market statistics and growth signals
Investor and enterprise momentum around Mistral has been strong. Reuters reported that a 2025 funding round valued the company at about €11.7 billion, with ASML becoming the biggest investor in that round.
On the enterprise side, partnerships signal real production adoption. Examples include a partnership expansion with SAP around “sovereign AI” positioning (Studio and Le Chat integration into SAP’s AI Foundation).
User demographics and behavior
Mistral’s user base tends to split into two clear groups:
Product users who start with Le Chat (personal productivity, summarizing, drafting, quick answers).
Builders and enterprises who use the API/Studio to embed AI inside workflows like internal copilots, document analysis, and secure deployments.
A very common behavior pattern is “try in assistant → prove value → roll into production,” especially in companies that need control over data and deployment.
Geographic presence
Mistral is globally accessible as a platform, but it’s especially relevant in Europe because of the “sovereign AI” narrative and partnerships with major European tech and telecom players. For example, Orange announced a strategic partnership with Mistral aimed at accelerating AI development in Europe.
Future projections
The direction of travel looks like this: more enterprise deployments, more sovereignty-focused rollouts, and more specialized models that trade “biggest possible” for “fast, efficient, deployable anywhere.” A recent example reported in early 2026 is Mistral releasing real-time speech/translation models designed to run locally with low latency—reflecting a push toward privacy and cost efficiency.
Opportunities for entrepreneurs
This massive success is why many entrepreneurs want to create similar platforms—because the market reward is huge for AI products that are: reliable, cost-aware, and deployable inside real organizations. Real opportunities include vertical copilots (legal, HR, finance), multilingual assistants for global teams, and “sovereign-by-design” AI stacks for regulated markets.
And the proof that businesses want this: Reuters reported HSBC signed a multi-year partnership with Mistral and planned to self-host its commercial models to support internal use cases like analysis, translation, and risk workflows.
This massive success is why many entrepreneurs want to create similar platforms…
Building Your Own Mistral AI–Like Platform
Why businesses want Mistral-style platforms
Companies want Mistral-like platforms because they need AI that can be rolled out across teams safely and quickly. The demand is especially strong for platforms that combine a friendly assistant experience (so users adopt it) with a developer/enterprise layer (so it can be embedded into products and internal workflows). The “sovereign AI” angle also matters for many organizations that want more control over data, hosting, and compliance expectations.
Key considerations for development
To build a Mistral-like AI platform, you need to design for both adoption and operations: a smooth end-user experience, plus a secure backend foundation that supports identity, governance, monitoring, and scalable inference. Your platform should also support knowledge-grounding (RAG) so answers can rely on trusted documents instead of guessing—this is one of the biggest requirements in enterprise deployments.
Read Also :- How to Market an AI Chatbot Platform Successfully After Launch
Cost Factors & Pricing Breakdown
Mistral AI–Like App Development — Market Price
| Development Level | Inclusions | Estimated Market Price (USD) |
|---|---|---|
| 1. Basic AI Model API & Assistant MVP | Core web interface and API layer for AI text generation, user registration & login, integration with a single LLM or hosted model, prompt → response workflows, basic inference endpoints, simple developer docs portal, API key management, standard admin panel, basic usage analytics | $90,000 |
| 2. Mid-Level AI Model Platform & Developer Ecosystem | Multi-model routing (text, embeddings, chat), model version management, workspace/projects, developer dashboard with API usage metrics, SDK samples, credits/usage tracking, analytics dashboard, stronger safety & moderation hooks, polished web UI and developer console | $180,000 |
| 3. Advanced Mistral AI–Level Foundation Model Ecosystem | Large-scale multi-tenant AI model platform with enterprise orgs & RBAC/SSO, fine-tuning pipelines, high-performance inference infrastructure, API gateway with scaling, audit logs, advanced observability, cloud-native scalable architecture, robust safety & policy enforcement | $300,000+ |
Mistral AI–Style Foundation Model Platform Development
The prices above reflect the global market cost of developing a Mistral AI-like foundation model platform and developer ecosystem — typically ranging from $90,000 to over $300,000+, with a delivery timeline of around 4–12 months for a full, from-scratch build. This usually includes model hosting or integration, inference APIs, developer tooling, analytics, governance controls, and production-grade cloud infrastructure capable of handling high-throughput AI workloads.
Miracuves Pricing for a Mistral AI–Like Custom Platform
Miracuves Price: Starts at $15,999
This is positioned for a feature-rich, JS-based Mistral AI-style AI model platform that can include:
- AI model inference APIs for text, embeddings, or conversational AI
- Integration with hosted models or external model providers
- Developer portal with API documentation and usage dashboards
- User accounts, projects/workspaces, and access controls
- Usage and credit tracking with optional subscription or pay-per-use billing
- Core moderation, compliance, and safety hooks
- A modern, responsive web interface plus optional companion mobile apps
From this foundation, the platform can be extended into fine-tuning workflows, enterprise AI governance, model marketplaces, dataset integrations, and large-scale AI SaaS deployments as your AI ecosystem matures.
Note: This includes full non-encrypted source code (complete ownership), complete deployment support, backend & API setup, admin panel configuration, and assistance with publishing on the Google Play Store and Apple App Store—ensuring you receive a fully operational AI platform ecosystem ready for launch and future expansion.
Delivery Timeline for a Mistral AI–Like Platform with Miracuves
For a Mistral AI-style, JS-based custom build, the typical delivery timeline with Miracuves is 30–90 days, depending on:
- Depth of AI model hosting and inference capabilities
- Number and complexity of model, storage, billing, and moderation integrations
- Complexity of enterprise features (RBAC, SSO, governance, audit logs)
- Scope of web portal, mobile apps, branding, and long-term scalability targets
Tech Stack
We preferably will be using JavaScript for building the entire solution (Node.js/Nest.js/Next.js for the web backend + frontend) and Flutter / React Native for mobile apps, considering speed, scalability, and the benefit of one codebase serving multiple platforms. Other tech stacks can be discussed upon request — Contact us
Essential features to include
- Integrations/tools: connectors to knowledge bases, ticketing, CRM, and internal systems
- Assistant UI with chat history, prompts, and conversation management
- Model gateway (API layer) with authentication, rate limits, and usage logging
- Role-based access control (RBAC) for teams and organizations
- Prompt templates and workspace-level configurations (tone, policies, guardrails)
- Retrieval (RAG) support: document upload, chunking, embeddings, vector search
- Citations/sources in answers for trust in business use cases
- Admin dashboard for users, permissions, usage limits, and compliance settings
- Monitoring: latency, quality feedback, error tracking, spend/cost dashboards
- Billing/subscriptions: plans, seat-based pricing, or usage-based add-ons
Read More :- AI Chat Assistant Development Costs: What Startups Need to Know
Conclusion
Mistral AI’s story shows what the market is really rewarding right now: not just powerful models, but platforms that make AI easy to adopt, safe to operate, and practical in real business workflows. Le Chat helps users experience value instantly, while the API/Studio layer helps organizations turn that value into production-grade features and internal copilots.
If you’re building in this space, the winning formula is simple: focus on trust, control, and deployment readiness. The assistant UI may get the attention, but the platform foundation—governance, monitoring, RAG grounding, and cost controls—is what turns AI into something companies can rely on every day.
FAQs :-
How does Mistral AI make money?
Mistral AI makes money through API/platform usage (businesses paying to use its models), paid plans for Le Chat (individual/team tiers), and enterprise contracts for organizations that need governance, security, and support.
Is Mistral AI available in my country?
Mistral’s products are internet-based, so access is generally broad, but availability can still depend on regional policies, compliance requirements, and the specific product tier you’re using.
How much does Mistral AI charge users?
Pricing depends on what you use. Le Chat has published tiers, while API usage depends on model selection and usage volume. The most accurate details are shown on Mistral’s official pricing page.
What’s the commission for service providers?
There’s no commission model. You pay for AI usage or plan tiers, and you decide how to monetize your own product (subscriptions, per-seat, usage-based add-ons).
How does Mistral AI ensure safety?
Mistral’s safety in practice is a combination of platform controls and how developers implement AI responsibly. For business-grade use, teams typically add grounding (RAG), permissions, logging, and review flows so outputs are reliable and auditable.
Can I build something similar to Mistral AI?
Yes, but building a full Mistral-like platform is a large project. You’d need model serving infrastructure, an API gateway, usage monitoring, safety systems, billing, and (for enterprise adoption) governance layers like RBAC and audit logs.
What makes Mistral AI different from competitors?
Mistral is often differentiated by its positioning as a major Europe-based AI platform, the combined approach of Le Chat + developer/enterprise platform, and its sovereignty/privacy narrative supported by partnerships and funding.
How many users does Mistral AI have?
Mistral does not consistently publish a single public global “user count” number for Le Chat or the API. Adoption is often reflected through partnerships, enterprise deals, and growth milestones reported in the press.
What technology does Mistral AI use?
Mistral provides model APIs (chat/completions) and embeddings endpoints that are used for semantic search and RAG-style applications. The platform layer (Studio/console) supports developer and enterprise usage with management and governance features.
How can I create an app like Mistral AI?
Start with an assistant UI + secure backend calling an AI API. Add RAG (document ingestion, embeddings, vector search) for trust, then add admin controls, monitoring, and billing. Miracuves can accelerate this with ready-to-launch modules for assistant UI, RAG architecture, and subscription billing.
Related Articles :-
Miracuves is an independent software development company. We are not affiliated with, connected to, sponsored by, or endorsed by any company or product named in this article.
Terms such as “X Clone” are used descriptively. It is how the software industry refers to building a platform with functionality comparable to a known service, and how clients search for it.
The entire design and codebase of our products is built by our own team. Our products contain no code, design, graphics, or content originating from any third-party website or applications.
All third-party names and marks referenced in this article are the property of their respective owners, referenced solely to identify the services discussed.